Running an evaluation
An evaluation scores a knowledge base against questions whose answers you already know, so a change to its content or settings shows up as a number rather than a hunch. You need a golden set before you can run one.
- The Knowledge Base app in your top bar.
- This permission: Knowledge Base · Analytics - Execute.
- A knowledge base with indexed documents and at least one golden set (see Building a golden set). An evaluation searches the whole knowledge base whatever the runner's own access, so this permission suits trusted people.
If Knowledge Base isn't in your top bar, your role can't view it or your plan doesn't include it. Ask a workspace administrator, or see Permissions and module visibility.
Steps
Start the run
Open the knowledge base, select Evaluation, then Run evaluation at the top right. It reads Starting…, then _Evaluation run started._ appears. There is no picker: the run uses the golden set added most recently.
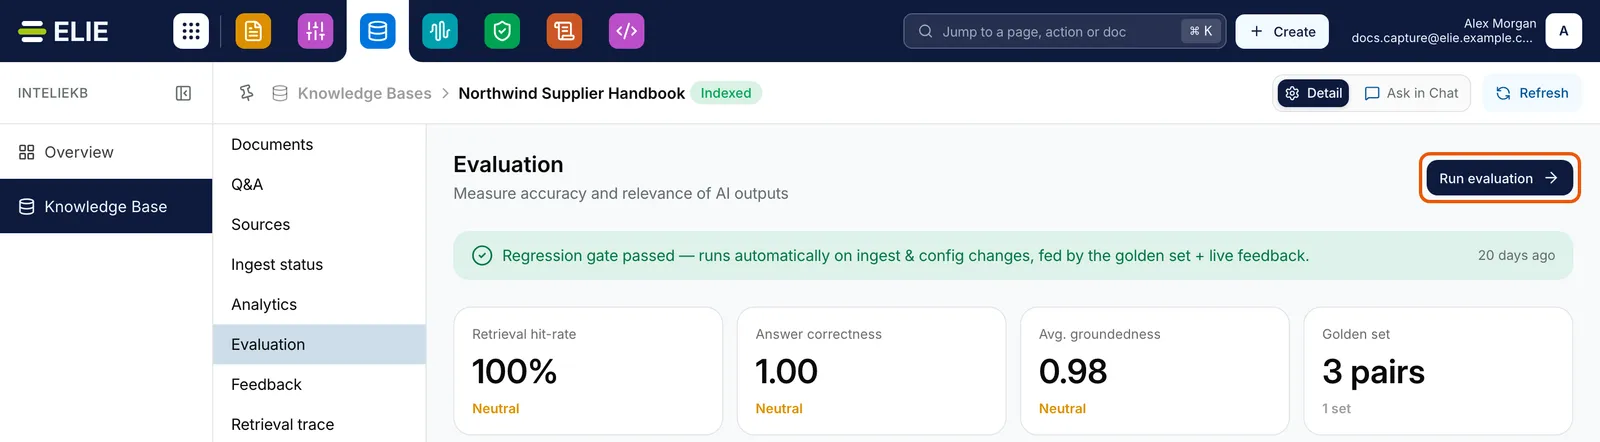
The Evaluation section of Northwind Supplier Handbook with the Run evaluation button ringed above the four figure cards. EnlargeOpen the run
The run is listed with Run, Trigger, Hit-Rate, Groundedness, Result and When. Select its Run number to open the Evaluation Run panel, which refreshes itself until the run finishes.
Read the metrics
Metrics gives Faithfulness, Answer relevancy, Context precision, Context recall, Groundedness and Retrieval hit-rate, each with its change vs baseline, under a verdict: No regression, Regression detected or No baseline. Per-item breakdown shows the same for each question.
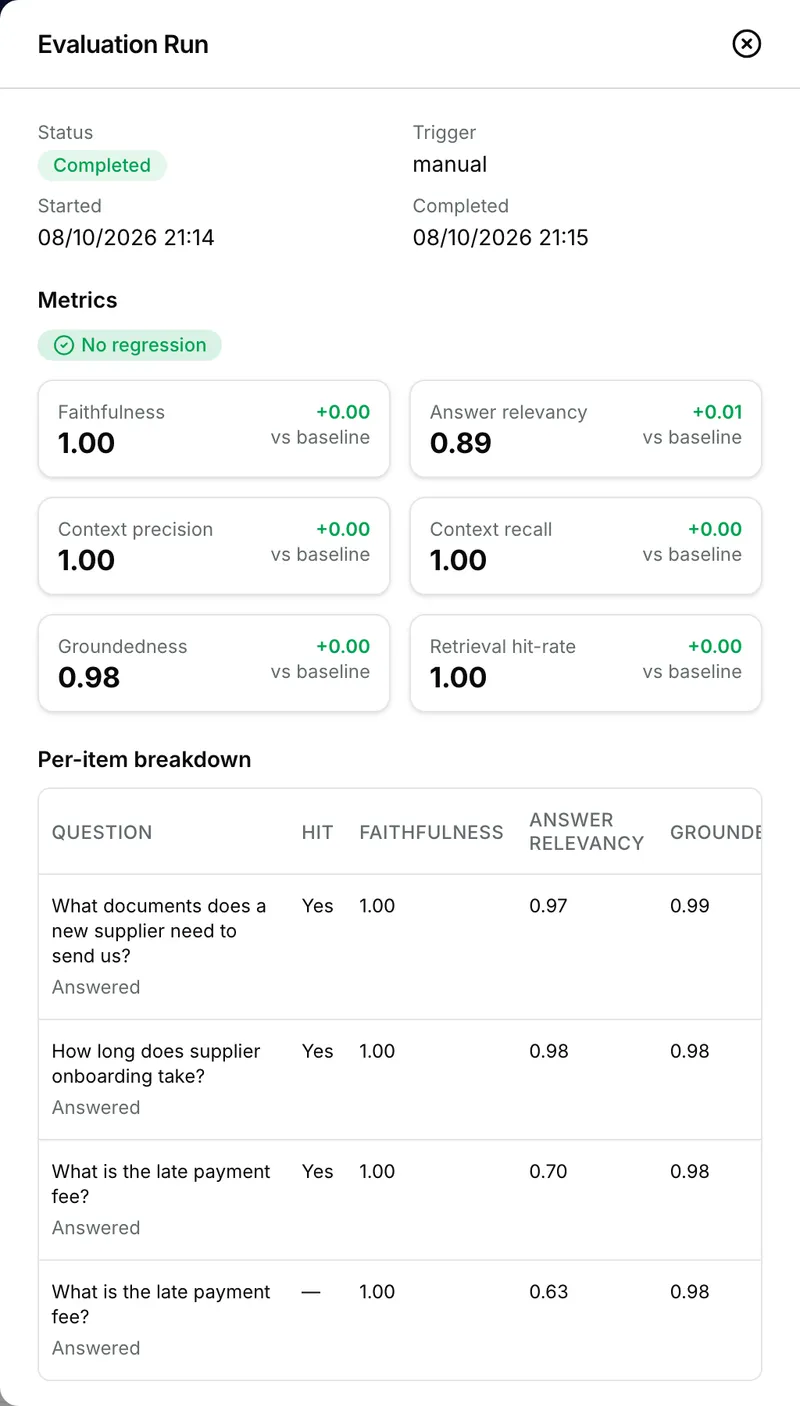
The Evaluation Run panel of a completed run: Status Completed, Trigger manual, No regression, six metrics each with its change vs baseline, and the per-item breakdown listing each question with its hit and scores. Compare over time
Back on the list, the cards show the latest finished run: Retrieval hit-rate, Answer correctness and Avg. groundedness, each with its change against the baseline or a rating such as Very strong, and the size of your Golden set. A banner above them states the verdict.
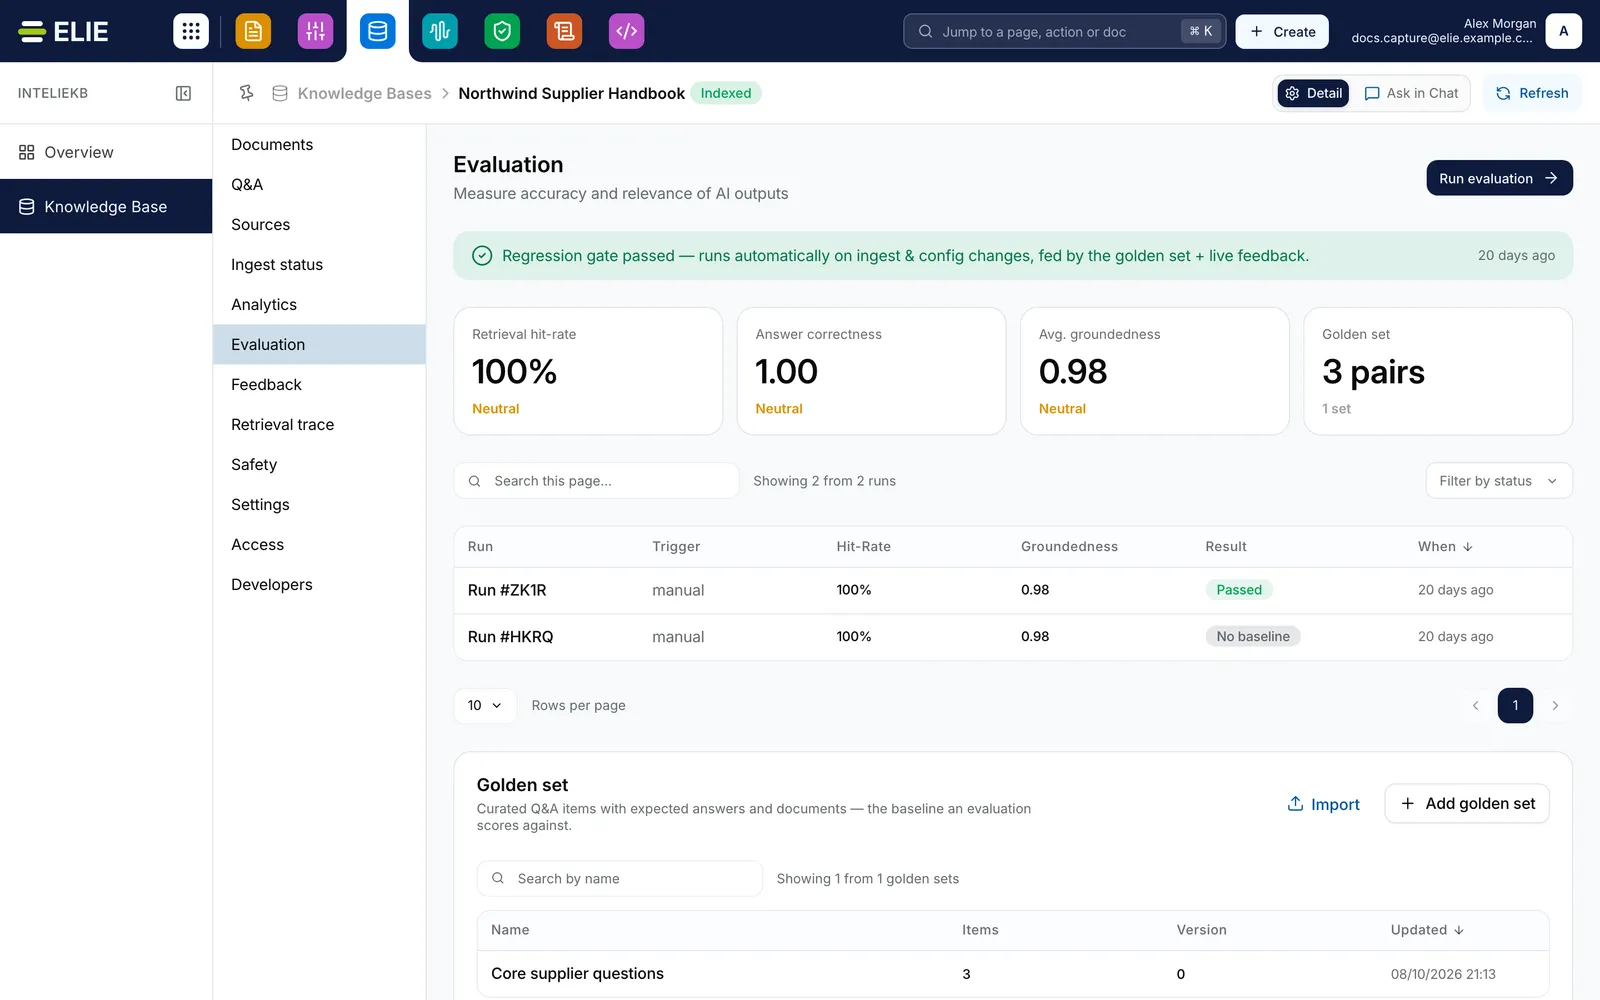
The Evaluation section: a green regression gate banner, Retrieval hit-rate 100%, Answer correctness 1.00, Avg. groundedness 0.98, Golden set 3 pairs, the runs list with one Passed and one No baseline, and the Golden set card. Enlarge


What success looks like
- The run's row carries a Hit-Rate, a Groundedness and a Result of Passed, Regression or No baseline.
- Metrics lists all six figures instead of the not-finished notice.
- The banner and the cards move with the new run.
Reading the verdict honestly
The verdict is information, not a gate: a regression stops nothing, and the red banner says so.
Answer correctness on the cards is the figure the panel calls Faithfulness. The first
finished run has nothing to compare with, so it reads No baseline and shows no banner; the
next run is compared with it. Every run you start shows manual under Trigger. The green
banner's mention of automatic runs on content changes only applies if that has been switched on
for the knowledge base outside this screen.
Search this page… and the status filter above the runs only narrow the runs already on the page.
If something goes wrong
| Symptom | Likely cause | What to do |
|---|---|---|
| Run evaluation is greyed out. | There is no golden set yet, or your role lacks Knowledge Base · Analytics - Execute. Hover it to see which. | Build a golden set, or ask a workspace administrator. |
| No metrics yet and a note that the run hasn't completed. | The run is still Queued or Running. | Leave the panel open; it refreshes. |
| The run reads Failed, with Evaluation failed and a reason. | The run stopped part-way. | Read the reason, fix what it names, then run again. |
| A banner starts Regression flagged. | A metric dropped against the baseline. | Open the run and compare Per-item breakdown with the previous one. |
Next
- Building a golden set - the questions a run asks.
- Reading a retrieval trace - why one question scored badly.
- Knowledge base settings - the levels a run measures.